Integration
Modlens
 By
The first vision plugin for DeepSeek Harness, and the vision bridge for every text-only coding agent. Paste an image, get structured JSON evidence (OCR, layout, semantics). | 全网最强 DeepSeek Harness 外挂视觉插件,为 DeepSeek、GLM 等纯文本模型外挂视觉能力,粘贴图片即得结构化 JSON 证据(OCR、版面、语义)。
README
<p align="center">
<img src="https://raw.githubusercontent.com/liustack/modlens/main/assets/banner.jpg" width="100%" alt="ModLens" />
</p>
<h1 align="center">ModLens</h1>
<p align="center"><b>Give a text-only model sight, and just paste the image.</b></p>
<p align="center">🥇 <b>The most capable vision plugin for DeepSeek Harness (dsh)</b> 🥇</p>
<p align="center">
<a href="./README.zh-CN.md">简体中文</a> ·
<a href="skills/modlens/references/configure.md">Configuration</a> ·
<a href="docs/troubleshooting.md">Troubleshooting</a> ·
<a href="docs/security.md">Security</a> ·
<a href="https://github.com/liustack/modsearch"><b>🔍 ModSearch (the best free web search plugin for DSH)</b></a>
</p>
<p align="center">
<a href="https://x.com/liustack"><img src="https://img.shields.io/badge/follow-%40liustack-black?style=flat-square&logo=x&logoColor=white" alt="Follow @liustack on X"></a>
<a href="https://www.npmjs.com/package/@liustack/modlens"><img src="https://img.shields.io/npm/v/@liustack/modlens?style=flat-square&label=npm&color=cb3837" alt="npm"></a>
<a href="https://nodejs.org"><img src="https://img.shields.io/node/v/@liustack/modlens?style=flat-square" alt="Node.js"></a>
<a href="LICENSE"><img src="https://img.shields.io/badge/license-MIT-blue?style=flat-square" alt="License"></a>
<img src="https://img.shields.io/badge/Not%20backed%20by-Y%20Combinator-FF6600?style=flat-square&logo=ycombinator&logoColor=white" alt="Not backed by Y Combinator">
<img src="https://img.shields.io/badge/users-unknown-lightgrey?style=flat-square" alt="Users unknown">
</p>
DeepSeek's flagship chat models, and GLM-5.3 itself, are text-only and cannot read images. GLM-5.3-Flash is native multimodal. ModLens is a plug-in vision engine that gives a text-only model sight. **ModLens reads images pasted straight into the chat**, no saving to a file and passing a path first.
## Talk to us
Issues are welcome any time: [open one](https://github.com/liustack/modlens/issues/new/choose). Follow the liustack WeChat official account, and come find me on X: **[@liustack](https://x.com/liustack)**. What you built with it, which harness you are on, and what should come next are all shared on WeChat and X. A proper community space is on the way.
## Highlights
**🥇 The most capable vision plugin for DeepSeek Harness (dsh):** install it instantly with one command: `npx -y @deepseek-ai/dsh plugin --profile web add @liustack/[email protected]`. See the [setup guide](docs/harness-setup.md) for installation and update details. If the command line is not your thing but you still want to try DSH, check out <a href="https://github.com/liustack/aimanager"><b>AIManager</b></a>, the lightest desktop wrapper for DeepSeek Harness. It gets you started with zero code or configuration and installs every dependency for you with one click.
Pasting an image works two ways. **① Just paste.** On a text-only model the pasted image lands as a private temp file and its path enters the composer (the same interaction OpenCode and Pi ship), then the `modlens_read_image` tool takes it from there. **② Pick a `(modlens vision)` entry** in the model selector (it remembers your choice, so once is enough), then paste: the thumbnail stays visible in your message, closer to the Codex app feel, and the image is converted to structured evidence at request time, answered by the same underlying route. The plugin auto-discovers every provider route carrying eligible text-only DeepSeek, GLM, or MiMo Pro models and adds a wrapped entry per route. A stock install gets **`DeepSeek-V4-Flash (modlens vision)`** and **`DeepSeek-V4-Pro (modlens vision)`**, while extra routes like opencode-go or zai get their own. Native vision models in those families, including GLM-5.3-Flash, are excluded automatically. Which paste route applies is the host's per-model call: only a model its metadata positively confirms text-only is taken over, anything unconfirmed is left alone, so vision models keep their native paste ([details](docs/harness-setup.md)).
**Paste images directly in every harness.** No saving to a file and passing a path first.
A hotkey that captures the screen into DeepSeek Harness is a separate plugin: [dsh-screenshot](https://github.com/paicat1/dsh-screenshot).
- **The lightest touch on the market.** No hooks, no wrappers, no local proxy daemon, not a single line changed in any harness config: on the skill harnesses it is exactly one skill folder, on dsh exactly one plugin. Uninstalling is deleting a folder, and your agents are back to stock.
- **Zero-config start.** Reuses existing setup in Claude Code, Codex, OpenCode, and Pi, plus other multimodal models already on your machine. Nothing installed locally? Antigravity CLI is a free no-key channel, and a free Gemini key brings a read down to 5-10 seconds. API keys from every major OpenAI-compatible provider work too.
- **Comma-separated keys rotate on auth, rate-limit, or quota failures.** Other failures skip remaining keys and keep the existing provider failover.
- **Evidence, not imagination.** Full transcription, reading-order layout regions, entity and relation lists. The model quotes specifics.
- **Install once, use everywhere.** Verified on real machines in Claude Code, Codex, Pi, and OpenCode.
## Install in other harnesses
**Option 1, install with [skills.sh](https://skills.sh/):**
```bash
npx -y skills add liustack/modlens --skill modlens --global
```
This installs the `modlens` skill at user level. Restart the harness, then ask
your AI to configure modlens and run its health check.
**Option 2, hand the install to your AI.** Send it this line:
> Install and configure the modlens skill following https://github.com/liustack/modlens/blob/main/INSTALL.md, then run the health check and tell me the result.
The install starts by checking what your machine already has. An existing login in Claude Code, Codex, OpenCode, or Pi can be enough: modlens asks before reusing any of them, and the health check tells you where things stand.
**After either option, only if the health check comes back empty, set up a free engine.** The recommended choice is a free Gemini API key (about three minutes at [Google AI Studio](https://aistudio.google.com), no credit card), which also makes every read 5-10 seconds. A free OpenAI-compatible key from another platform works too. To avoid any sign-up, install Antigravity CLI instead, then sign in:
```bash
curl -fsSL https://antigravity.google/cli/install.sh | bash
agy # sign in, then exit
```
The install also inventories vision reachable through your other local harness CLIs (Codex, OpenCode, Pi) and asks, per harness, whether modlens may reuse it. Granted logins join the engine pool as equals, and every reused read is labeled with whose quota it spent.
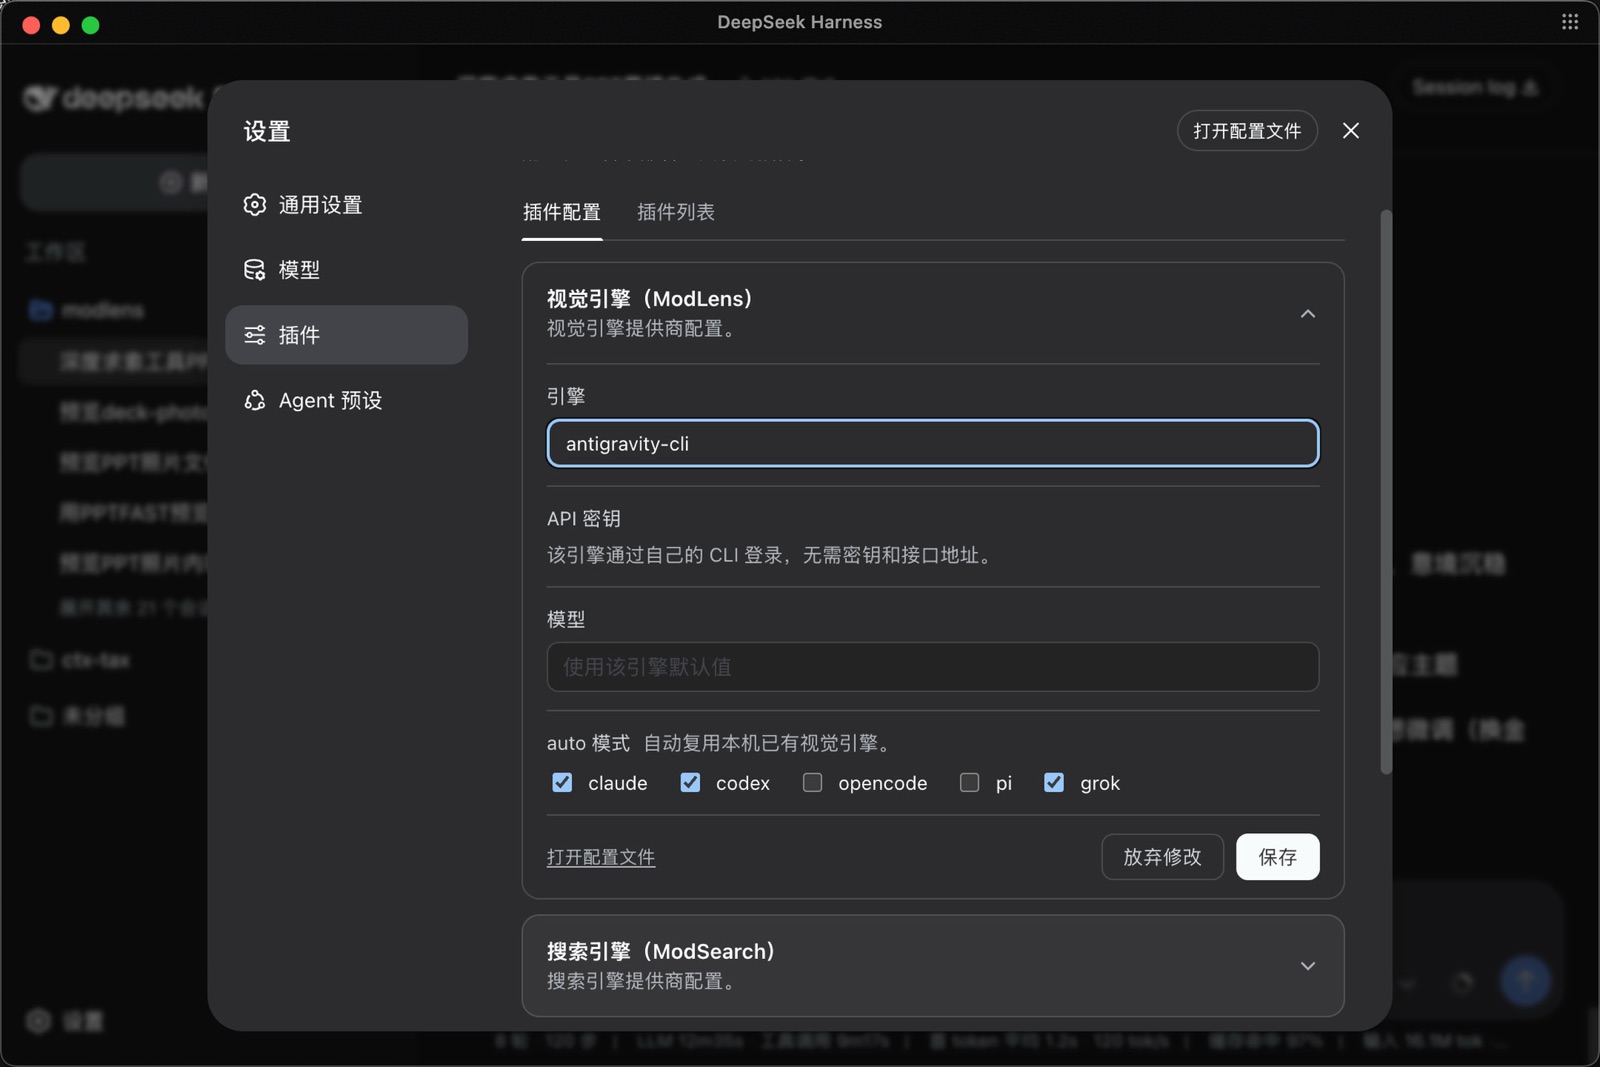
On DeepSeek Harness the command line is not the only way in. Settings → Plugins → Plugin config carries a ModLens card (from dsh 0.1.7 on, open the sidebar's Plugins page and pick `@liustack/modlens` under Installed): switch the engine, tick which local CLIs `auto` mode may reuse, hit save and it takes effect.
## Usage
Once installed, just chat. Paste an image or drop a path, ask anything, and the skill triggers on its own: the image goes to a vision engine and the answer comes back grounded in what it read. Paste once, and later questions about the same image do not need another paste.
## Vision engines: six built-in providers, four reusable CLIs, one failover chain
ModLens does not depend on any single vision service. Ten sources of vision in total: six built-in providers, any one of which is enough, plus four local agent CLIs whose logins can be reused. The built-ins:
| Provider | What it needs | Speed per read | Good for |
| :-- | :-- | :-- | :-- |
| `gemini-api` | a free Gemini API key ([3 minutes, no card](https://aistudio.google.com)) | 5-10s | the recommended default |
| `openai` | any OpenAI-compatible endpoint (key + baseUrl + model) | 5-10s | qwen-vl, GLM, self-hosted gateways |
| `anthropic` | an Anthropic API key | 5-10s | machines already holding one |
| `antigravity-cli` | the free `agy` CLI, one browser sign-in, no key | 15-45s | zero-signup starts |
| `claude-cli` | a signed-in Claude Code | 20-45s | riding your existing Claude subscription |
| `kimi-cli` | a signed-in Kimi Code | 20-45s | riding your existing Kimi subscription, named explicitly |
Without a pinned provider, every configured engine forms one failover chain: the fast API providers try first, the agent CLIs back them up, the first good result wins, and `meta.attempts` records every attempt so a fallback is never silent.
### `openai` is a universal socket, not just OpenAI
Any endpoint speaking the OpenAI chat-completions protocol with image input plugs straight in — that covers most of the vision-model world:
```bash
modlens config set openai.baseUrl https://dashscope.aliyuncs.com/compatible-mode/v1 # qwen-vl
modlens config set openai.apiKey <key>
modlens config set openai.model qwen3-vl-plus
```
`apiKey` (and the matching env var) also accepts a comma-separated list. ModLens rotates to the next key after authentication, rate-limit, or quota failures. Network, 5xx, and parse failures skip remaining keys and keep provider failover.
The same three keys work for GLM's open platform, SiliconFlow, OpenRouter, a self-hosted vLLM/Ollama, or any gateway of your own. If your favorite vision model has an OpenAI-compatible API, ModLens can drive it.
### Reusing what your machine already has
Two more sources of vision need zero new keys, each behind one explicit consent recorded in config:
- **The harness you are talking in right now.** Running inside Claude Code with
... (truncated)
integration


Comments
Sign in to leave a comment